Soumyadeep Roy

Postdoctoral Scholar · Stanford University

Division of Computational Medicine · Department of Medicine

Soumyadeep Roy

About

I am a postdoctoral scholar working with Prof. Tina Hernandez-Boussard in the Division of Computational Medicine, Department of Medicine, Stanford University. My research is on responsible reasoning for AI-assisted clinical decision making, at the intersection of biomedical AI, machine learning and natural language processing.

I design and evaluate clinical AI systems on real-world patient data — structured EHR and clinical notes — across Parkinson’s disease (L3S Research Center & Hannover Medical School), oncology (Wipro GE Healthcare) and postoperative pain management (Stanford Medicine). My work spans reliability evaluation of medical LLMs, RAG systems and agents; guideline-grounded clinical decision support; efficient pretraining of biological foundation models; and domain adaptation for medical text.

I received my PhD in Computer Science and Engineering from IIT Kharagpur (thesis: Domain Adaptation for Medical Language Understanding). My work has appeared at venues including ACL, IJCAI, SIGIR, EMNLP, ECAI, LREC, CIKM and Frontiers in Artificial Intelligence.

Education

Research

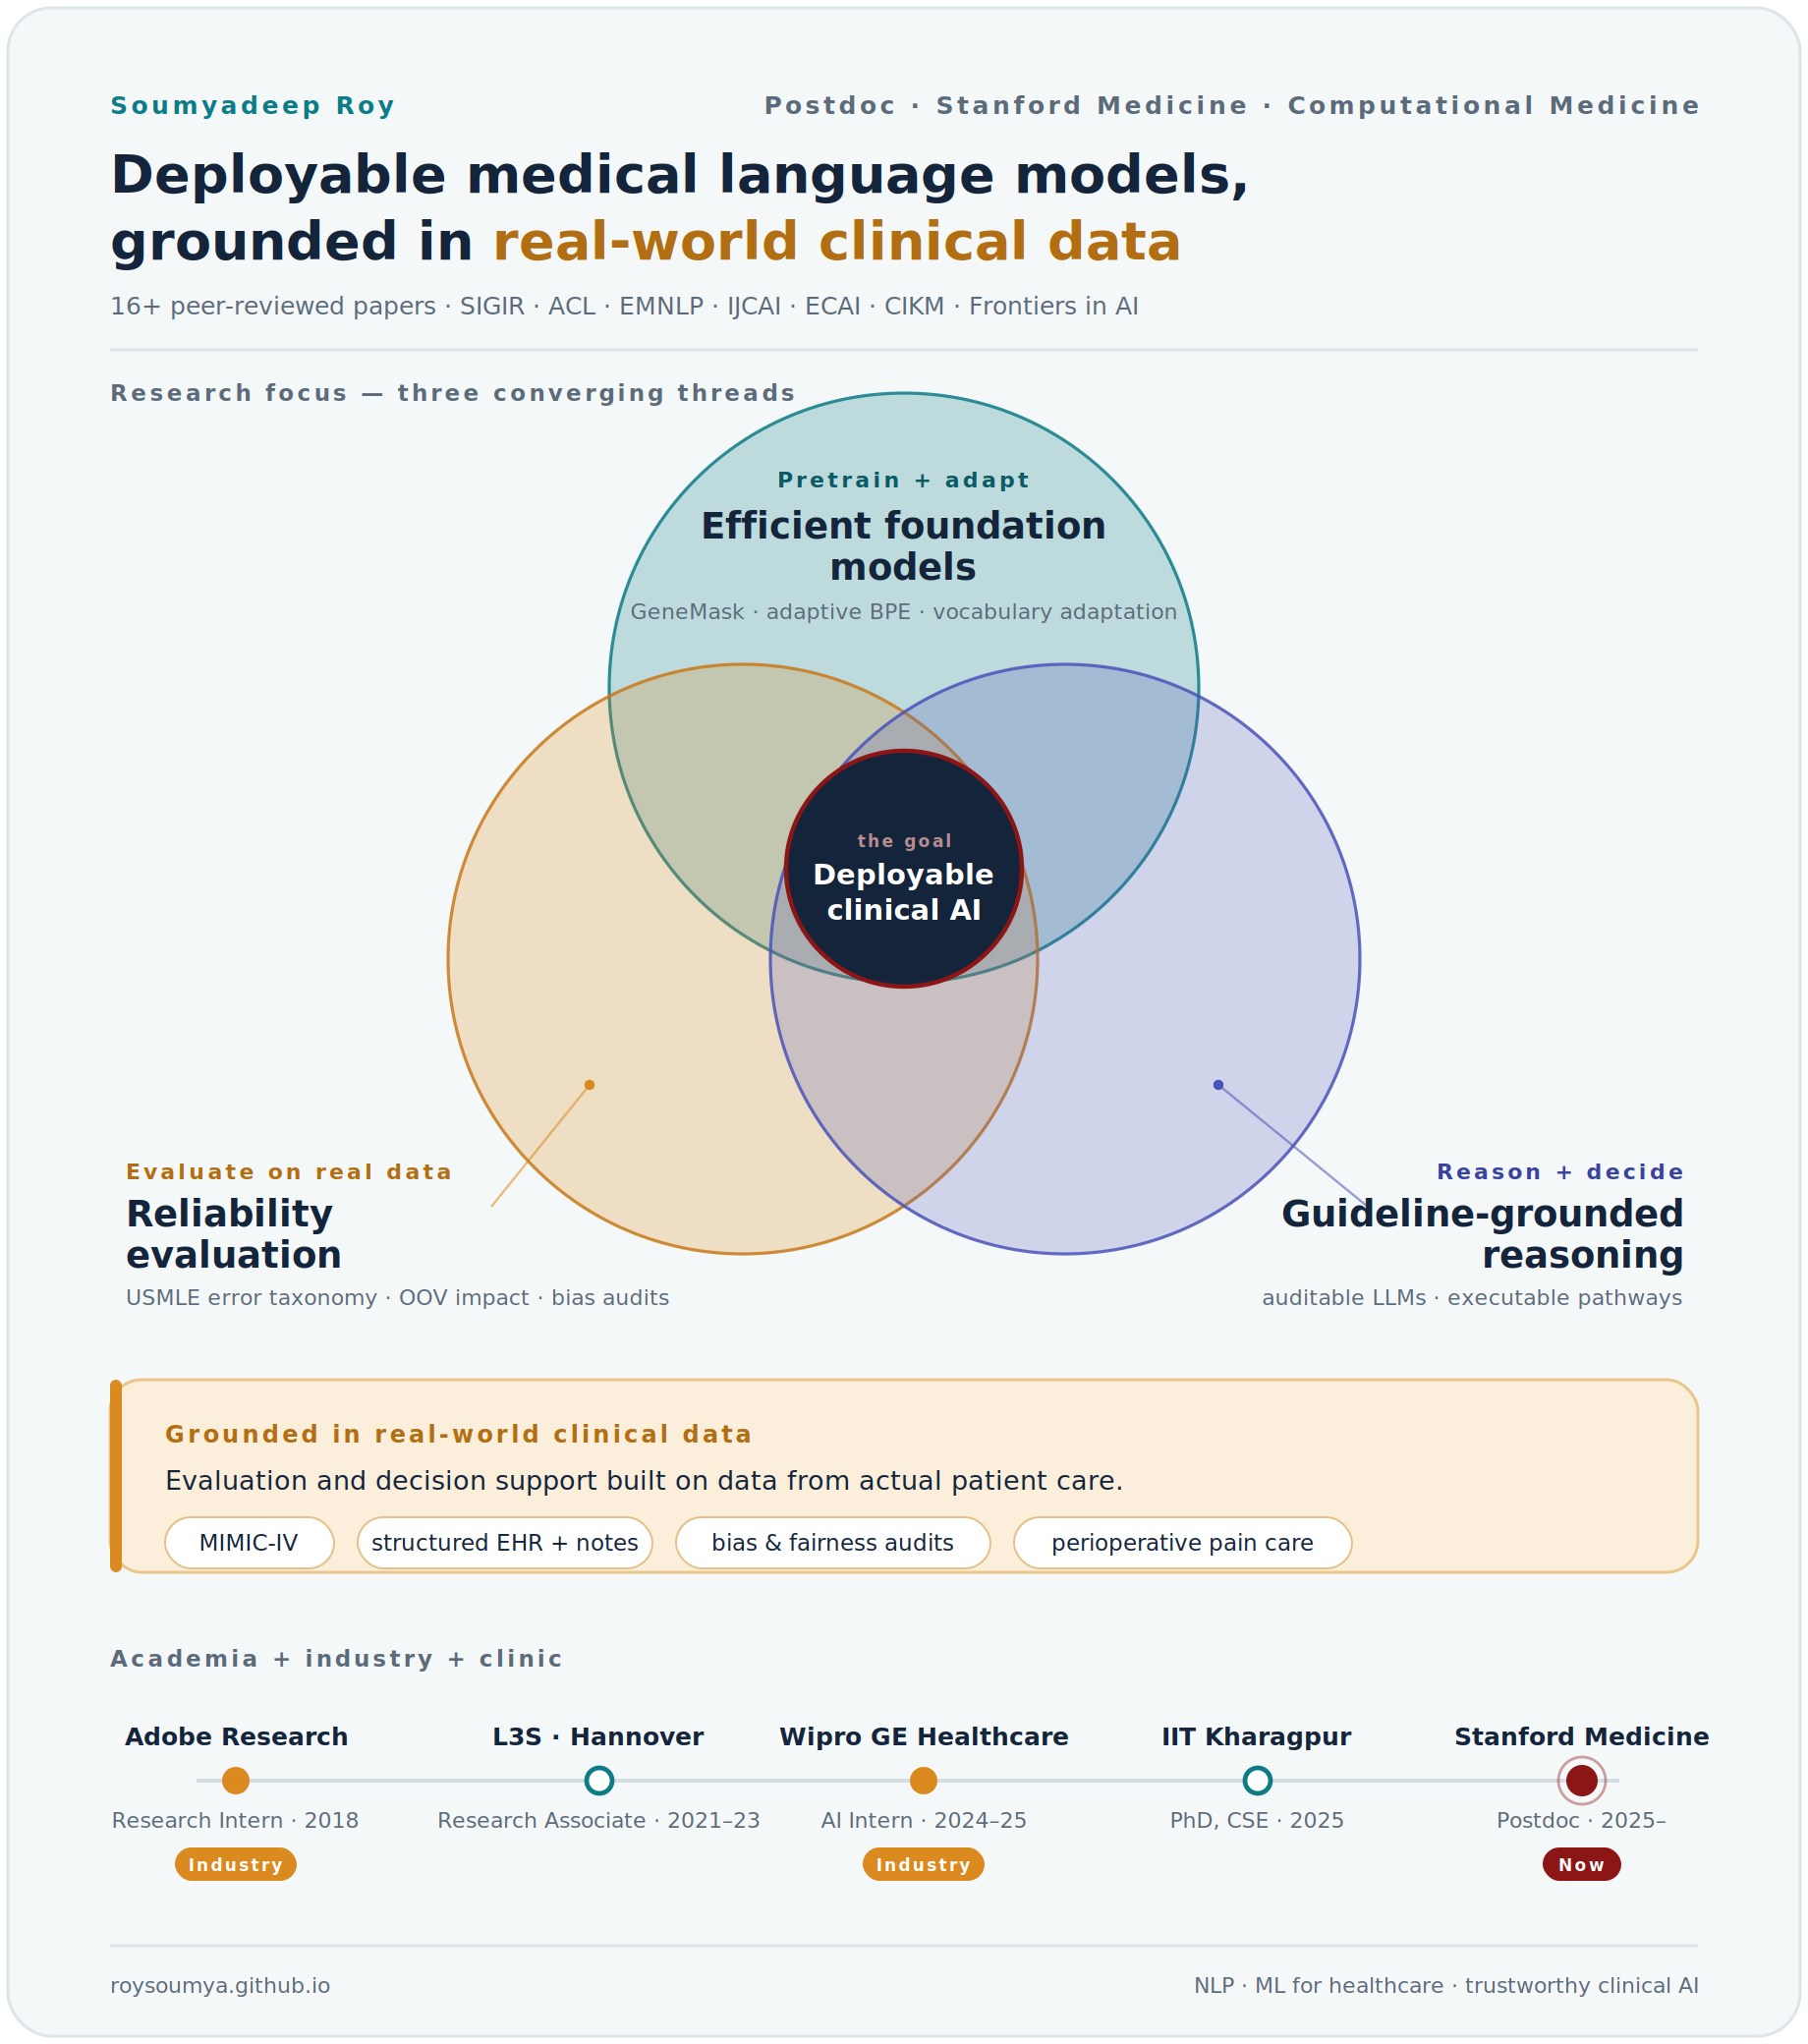
My central question is how prescriptive knowledge sources — above all, clinical guidelines — can be used to build scalable, data-driven approaches that ensure the evidence quality and reliability of AI-assisted clinical decision making. I work on this in two connected directions.

Reliability measurement. I study how model reasoning varies under controlled, clinically grounded counterfactuals, and use that variation to estimate how a system will behave after deployment. This includes measuring invariance and sensitivity in synthetic patient trajectories for evaluating patient-to-trial matching (TrialEval), counterfactuals built on clinical risk factors (Q-Pain++), and trajectory-level metrics for rare, compounding failures in sequential clinical agents (cascading tail risk).

Reliability mitigation. Grounding model context in the relevant guideline details leads to more accurate dosage recommendations and better robustness to decision-space framing. In parallel, I build models that compute guideline deviations in real-world patient care trajectories from Stanford Health Care and MIMIC data, to ask whether a deviation leads to better outcomes or avoidable harm.
Research questions I’m interested in
  • How do real-world patient trajectories deviate from clinical guidelines — and when does a deviation help or harm?Can we turn guidelines into computable pathways and measure deviations at scale over longitudinal EHR data and clinical notes?
  • How can we estimate a clinical LLM’s post-deployment behaviour before it is deployed?Which controlled, clinically grounded counterfactuals reveal whether a model’s reasoning is invariant where it should be and sensitive where it must be?
  • Why are binary safety audits inadequate for frontier clinical models?How much of a model’s treatment decision is driven by how the decision space is framed, rather than by the patient in front of it?
  • How do small errors compound in sequential clinical agents?Can trajectory-level tail-risk metrics surface rare, escalating harms that per-step accuracy hides — for example in opioid prescribing after surgery?
  • Does uncertainty quantification flag the errors that matter clinically?How do we build decision-aware evaluations and scale-independent uncertainty measures that prioritise high-risk mistakes?
  • How can we make foundation models for medicine and biology cheaper to adapt?Can vocabulary adaptation and smarter masking cut pretraining and fine-tuning cost without sacrificing faithfulness on specialised text and genomic sequences?
Research career overview

Methods, frameworks & datasets

FrameworkQ-Pain++

Factorial stress-testing and multi-modality evaluation of clinical LLMs. An audit of five models exposed a decision-space framing effect driving ~92% of treatment-decision changes; guideline grounding improves robustness.

FrameworkCascading Tail Risk

Trajectory-level safety evaluation for sequential clinical LLM agents, with Tail Harm Escalation and Tail-Restricted Wasserstein Distance metrics, demonstrated on postoperative opioid prescribing.

MethodGeneMask

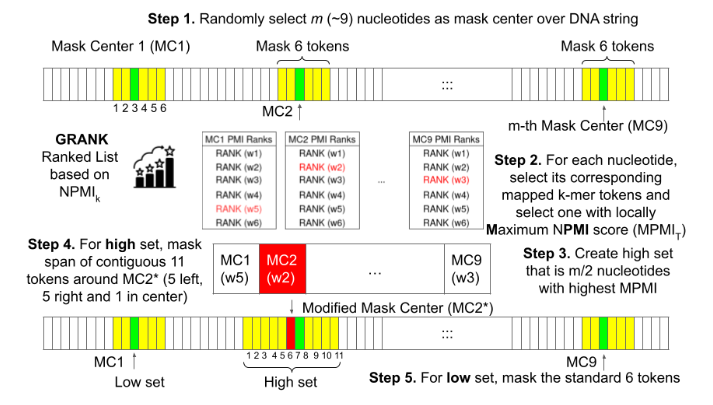
NPMI-guided masking for masked language modelling of DNA sequences. 10× faster pretraining for few-shot gene sequence classification with DNABert and LOGO.

MethodCurriculum GeneMask↳ from GeneMask

Adaptive curriculum masking for DNA transformers, improving genome-understanding benchmarks in both full-data and few-shot settings.

MethodMEDVOC

Vocabulary adaptation for medical summarization, with fragment-score-based hyperparameter search that cuts fine-tuning time from 450 days to about 45 hours.

MethodVocabReplace-Then-Expand

Parameter-efficient vocabulary adaptation for LLMs: adds domain tokens while replacing under-trained ones. 35–55% less training time than continual pretraining, 37% fewer parameters.

MethodAdaptBPE

Modifies BPE initialisation so domain-specific terminology is preserved during fine-tuning of pretrained language models.

MethodDecision-tree PD subtyping

Interpretable Parkinson’s disease subtyping on the MJFF LRRK2 cohort (1,500+ patients); six subtypes externally validated on the MDS dataset.

DatasetG4UE — GPT-4 USMLE errors

GPT-4 responses to USMLE questions with a medical-expert error taxonomy of 8 failure modes and span-level annotations by 44 medical experts.

DatasetLongTailQA

A disambiguated long-tail QA benchmark addressing 8–30% entity ambiguity in existing datasets; query disambiguation gives RAG models up to 24.7% accuracy gains.

DatasetPhysician intent in dialogues

Annotated doctor–patient dialogues for physician intent modelling; intent filtering improves dialogue summarization.

DatasetMulti-disease trial search set↳ from MPSS

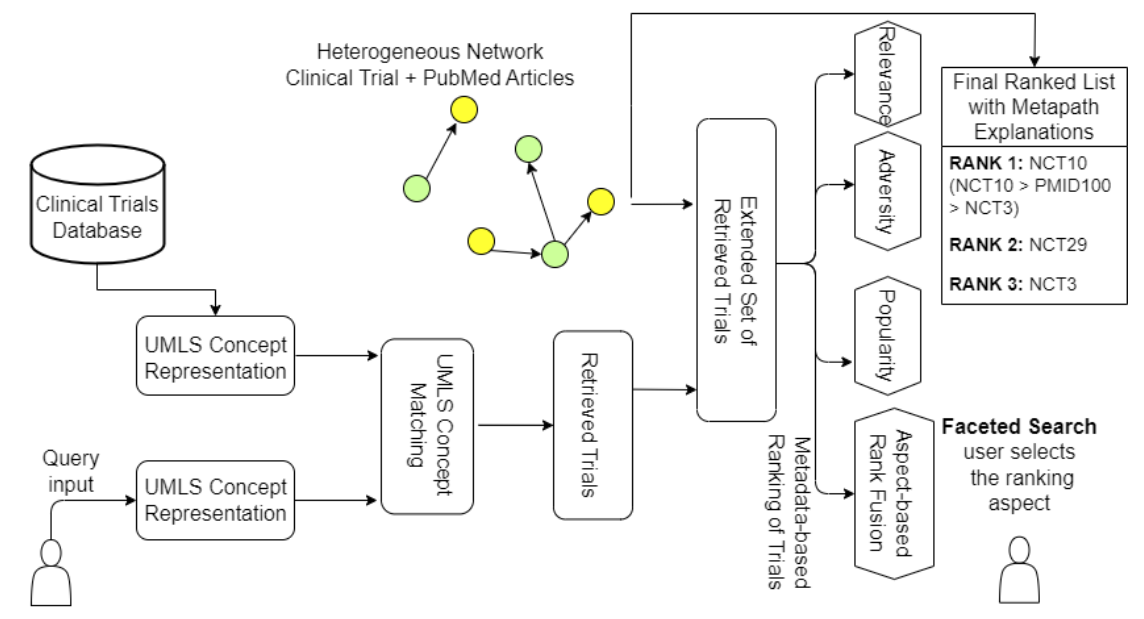
~25 consumer queries with ~95 annotated clinical trials each, released with a metapath-based trial search model over a 750K-node PubMed–trial graph.

Publications

Google Scholar  ·  DBLP

Under review

  1. Tail
    risk

    Cascading Tail Risk: Trajectory-Level Safety Evaluation for Sequential Clinical LLM Agents

    S. Roy, et al.

    Under review

  2. Q-Pain
    ++

    Beyond Binary Audits: Does Guideline Grounding Mitigate Decision-Space Framing in LLM Opioid Prescribing?

    S. Roy, K. Yu, et al.

    Introduces Q-Pain++, a factorial stress-testing framework auditing five clinical LLMs.

    Under review

  3. UQ

    A decision-aware evaluation suite for uncertainty quantification in clinical ML

    S. Roy, et al.

    Proposes the scale-independent Uncertainty Index; shows standard UQ methods fail to flag high-risk errors across three real-world datasets.

    Under review

2026

  1. ACL
    2026

    Learning Faster with Better Tokens: Parameter-Efficient Vocabulary Adaptation for Specialized Text Summarization

    G. Balde, S. Roy, M. Mondal, N. Ganguly.

    ACL 2026 · Main conference

  2. LREC
    2026

    LongTailQA: Benchmarking LLMs and RAG Models on Disambiguated Long-Tail Entities

    W. Xion, U. Hadler, T. Cofala, M. Idahl, S. Roy, W. Nejdl.

    LREC 2026

2025

  1. Front.
    AI

    Decision tree-based approach to robust Parkinson’s disease subtyping using clinical data of the Michael J. Fox Foundation LRRK2 cross-sectional study

    S. Roy, S. Krähe, M. Marschollek, et al.

    Frontiers in Artificial Intelligence

  2. ECAI
    2025

    “Where does it hurt?” — Dataset and Study on Physician Intent Trajectories in Doctor–Patient Dialogues

    T. Rohr, S. Roy, F. A. Mohamad, J.-M. Papaioannou, W. Nejdl, F. Gers, A. Löser.

    ECAI 2025

  3. ACL
    2025

    Evaluation of LLMs in Medical Text Summarization: The Role of Vocabulary Adaptation in High OOV Settings

    G. Balde, S. Roy, M. Mondal, N. Ganguly.

    Findings of ACL 2025

  4. WSDM
    2025

    Building Trustworthy AI Models for Medicine: From Theory to Applications

    S. Roy, S. S. Sundaram, D. Wolff, N. Ganguly.

    WSDM 2025 · Tutorial

  5. WSDM
    Day

    A Systematic Evaluation of Single-Cell Foundation Models on Cell-Type Classification Task

    N. Steiner, Z. Li, O. Vosoughi, J. Schrader, S. Roy, W. Nejdl, M. Tang.

    WSDM Day 2025

2024

  1. SIGIR
    2024

    Beyond Accuracy: Investigating Error Types in GPT-4 Responses to USMLE Questions

    S. Roy, A. Khatua, F. Ghoochani, U. Hadler, W. Nejdl, N. Ganguly.

    SIGIR 2024 · Resource & Reproducibility track
  2. IJCAI
    2024

    MEDVOC: Vocabulary Adaptation for Fine-tuning Pre-trained Language Models on Medical Text Summarization

    G. Balde, S. Roy, M. Mondal, N. Ganguly.

    IJCAI 2024 · Main track

  3. EMNLP
    2024

    Adaptive BPE Tokenization for Enhanced Vocabulary Adaptation in Finetuning Pretrained Language Models

    G. Balde, S. Roy, M. Mondal, N. Ganguly.

    Findings of EMNLP 2024

  4. ECAI
    2024

    Unlocking Efficiency: Adaptive Masking for Gene Transformer Models

    S. Roy, S. Sural, N. Ganguly.

    ECAI 2024

2023

  1. ECAI
    2023

    GeneMask: Fast Pretraining of Gene Sequences to Enable Few-Shot Learning

    S. Roy, J. Wallat, S. S. Sundaram, W. Nejdl, N. Ganguly.

    ECAI 2023

  2. ICDH
    2023

    Interpretable Clinical Trial Search using PubMed Citation Network Best student paper candidate

    S. Roy, N. Ganguly, S. Sural, K. Rudra.

    IEEE ICDH 2023

Earlier work (2021–2018) →

2021

  1. CIKM
    2021

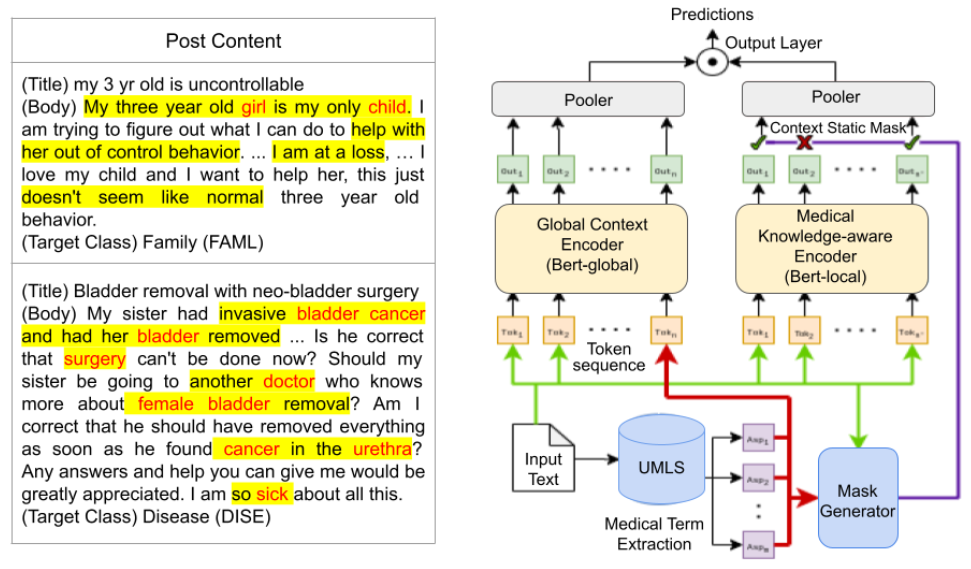
    Knowledge-Aware Neural Networks for Medical Forum Question Classification

    S. Roy, S. Chakraborty, A. Mandal, G. Balde, P. Sharma, A. Natarajan, M. Khosla, S. Sural, N. Ganguly.

    CIKM 2021

  2. TWEB
    2021

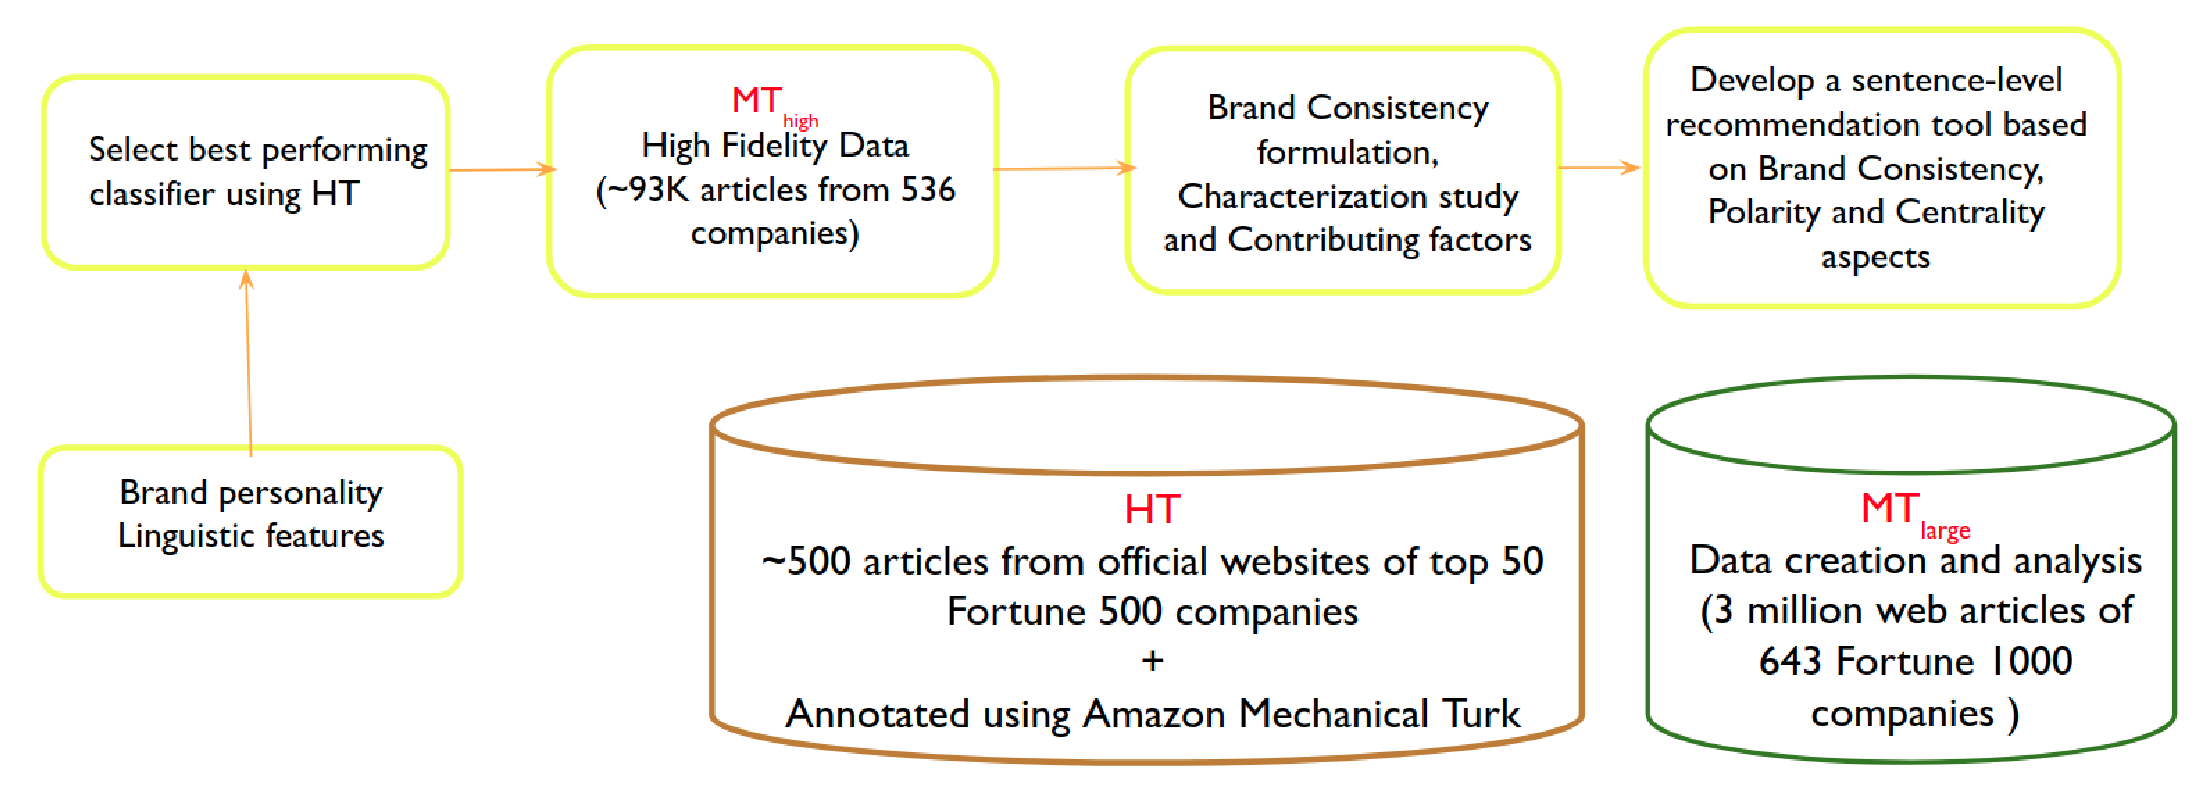
    An Integrated Approach for Improving Brand Consistency of Web Content: Modeling, Analysis, and Recommendation

    S. Roy, S. Sural, N. Chhaya, A. Natarajan, N. Ganguly.

    ACM Transactions on the Web

2019–2018

  1. WebSci
    2019

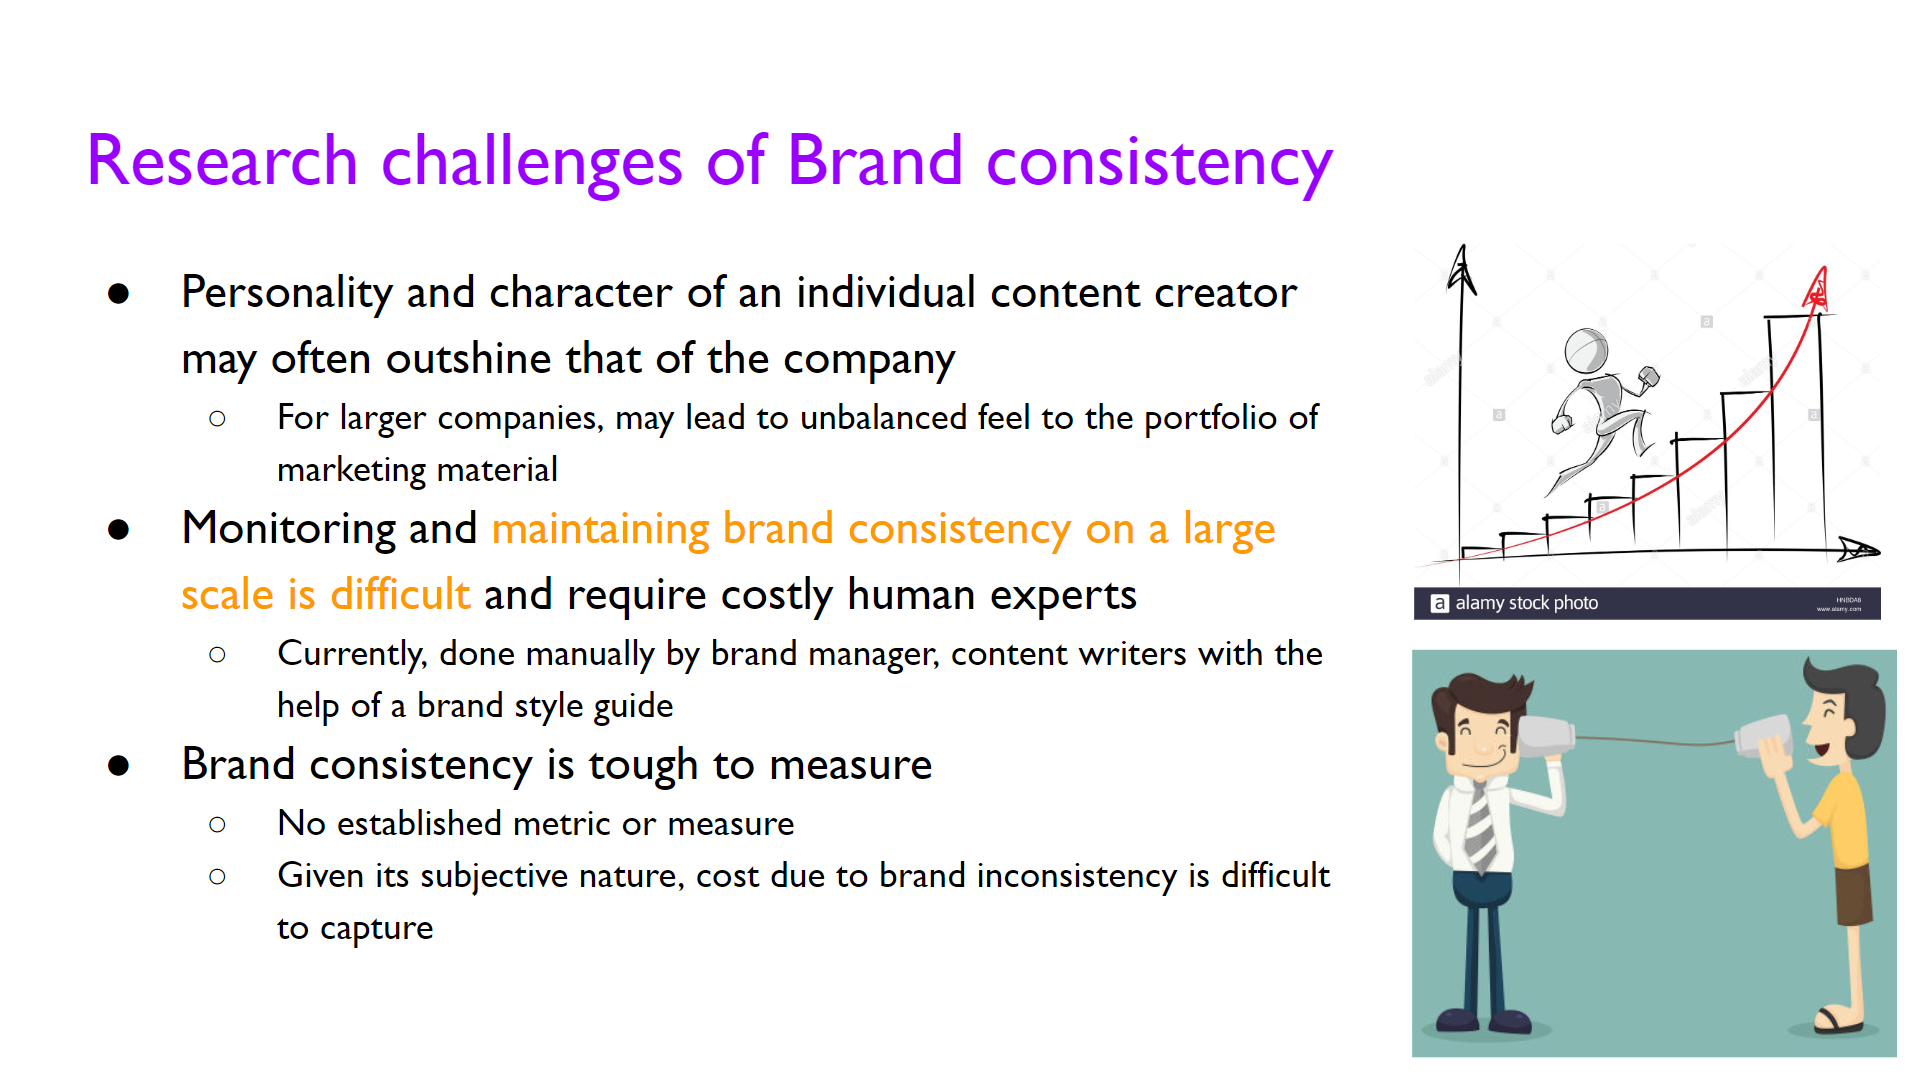
    Understanding Brand Consistency from Web Content

    S. Roy, N. Ganguly, S. Sural, N. Chhaya, A. Natarajan.

    ACM WebSci 2019

  2. CSoNet
    2019

    Towards an Aspect-Based Ranking Model for Clinical Trial Search

    S. Roy, et al.

    Computational Data and Social Networks (CSoNet) 2019

  3. CICBA
    2018

    Understanding Email Interactivity and Predicting User Response to Email

    S. Roy, et al.

    CICBA 2018

Experience

  • SU

    Postdoctoral Scholar, Division of Computational Medicine

    Stanford University · Stanford, CA · 09/2025–present

    • Lead three projects identifying failure modes in clinical LLMs — decision-space framing, cascading tail risk, and robustness under controlled clinical counterfactuals — and mitigations grounded in clinical guidelines.
    • Build and evaluate LLM-based clinical decision support for guideline adherence over real-world patient trajectories and for synthetic cohort generation to evaluate patient-to-trial matching systems.
    • Develop computable guideline pathways and deviation analysis over Stanford Health Care and MIMIC data (structured EHR and clinical notes).
  • GE

    PhD AI Intern, HealthCare Technology and Innovation Center

    Wipro GE Healthcare · Bangalore, India · 11/2024–05/2025

    • Built a generative-AI dashboard over oncology patient data (Chroma, LangChain) for semantic search across complex patient histories.
    • Developed representation learning for medical-imaging-equipment sensor logs for anomaly detection and predictive maintenance; one patent filed.
  • L3S

    Research Associate

    L3S Research Center, Leibniz University Hannover · Germany · 01/2021–06/2023

    • Led a collaboration with Hannover Medical School on Parkinson’s disease subtyping using the MJFF LRRK2 dataset; six novel subtypes externally validated on the MDS dataset.
    • Developed GeneMask, PMI-based token masking for DNA transformers with a 10× speedup for few-shot gene sequence classification.
  • ADBE

    Research Intern, Big Data Experience Lab

    Adobe Systems India · Bangalore, India · 05/2018–06/2018

    • Built brand-personality detection and brand-aligned sentence recommendation models; led a quality-controlled Amazon Mechanical Turk annotation study. Resulted in ACM WebSci 2019 and ACM TWEB 2021 papers.

Applied & translational work

  • 2026

    MIT Hacking Medicine — Boston GrandHackCo-developed AuriCare, a holistic pain-management decision-support concept. DemoBlogEvent

  • 2025–

    Computable guideline pathways at StanfordComputing deviations in patient care trajectories with Stanford Health Care and MIMIC data.

  • 2025

    Patent filing — Wipro GE HealthcareCo-inventor: deep-learning representation learning for medical-imaging-equipment sensor logs, enabling anomaly detection and predictive maintenance.

  • 2024

    Funded translational project — AI4ICPS, IIT KharagpurMy PhD work on interpretable clinical trial search continues as a funded project led by a co-author. ProjectPoster

Teaching

Lecture and workshop material is linked where available.

Stanford University

Leibniz University Hannover · Germany

NLP

Natural Language Processing

Teaching Assistant · Winter 2021

Retrieval

Foundations of Information Retrieval

Teaching Assistant · Summer 2022, 2023

IIT Kharagpur

Programming

Teaching Assistant

  • Programming and Data Structure Lab · Spring 2018
  • Information Retrieval · Autumn 2020
  • Computing Lab 1 · Autumn 2023
  • Department Website Team · Autumn 2018–Spring 2020

Tutorials & invited talks

  • Jan 2026

    Foundation Models for Medical TextAI Foundation Models in Biomedicine course, Leibniz University Hannover Slides

  • Jan 2026

    Building a Career in AI for Industry and AcademiaGoogle Developer Group on Campus, Kalyani Government Engineering College Slides

  • Dec 2025

    Vocabulary Adaptation Strategies for Finetuning Medical Language ModelsBreakfast Talk series, Microsoft Research India, Bangalore Slides

  • Aug 2025

    Improving Training Efficiency of DNA Foundation Models1st Symposium on Intersections: Statistical Genomics and Complex/Chronic Disease Biology, BRIC–NIBMG, Kalyani

  • Mar 2025

    Tutorial — Building Trustworthy AI Models for MedicineWSDM 2025 (3-hour tutorial) WebsiteSlides

  • Dec 2024

    Foundation Models for Medical TextAI Foundation Models in Biomedicine course, Leibniz University Hannover Slides

Mentoring & service

Mentoring

  • 3 MS students (2026)Bioengineering and Biomedical Data Science at Stanford; Biostatistics at Yale.
  • 1 PhD thesis, IIT Kharagpur (2026)Efficient vocabulary adaptation of general-purpose language models to the medical domain.
  • 3 M.Tech theses, IIT KharagpurClinical trial search (2019), query-focused medical summarization (2020), medical knowledge graphs for NLP (2021).
  • 1 B.Tech thesis, IIT Kharagpur (2022)Question generation for QA-based summary evaluation.

Reviewing & memberships

  • CORE A* conferencesNeurIPS 2026, FAccT 2026, AAAI 2023–2026, ACL Rolling Review (2025–2026 cycles), ACL 2023, EMNLP 2022–2023.
  • CORE A conferencesCOLING 2025, ML4H 2024, EACL 2023, ECML-PKDD 2020.
  • Medical AI & informaticsAMIA 2026, JAMIA, Frontiers in AI, Frontiers in Genetics, KAIS, IEEE TCDS, Artificial Intelligence in Medicine.
  • MembershipsSigma Xi, Association for Computational Linguistics, AMIA.